CALUM HALL
Graduate Software Engineer & Cybersecurity Enthusiast
|
|
>> About Me
|
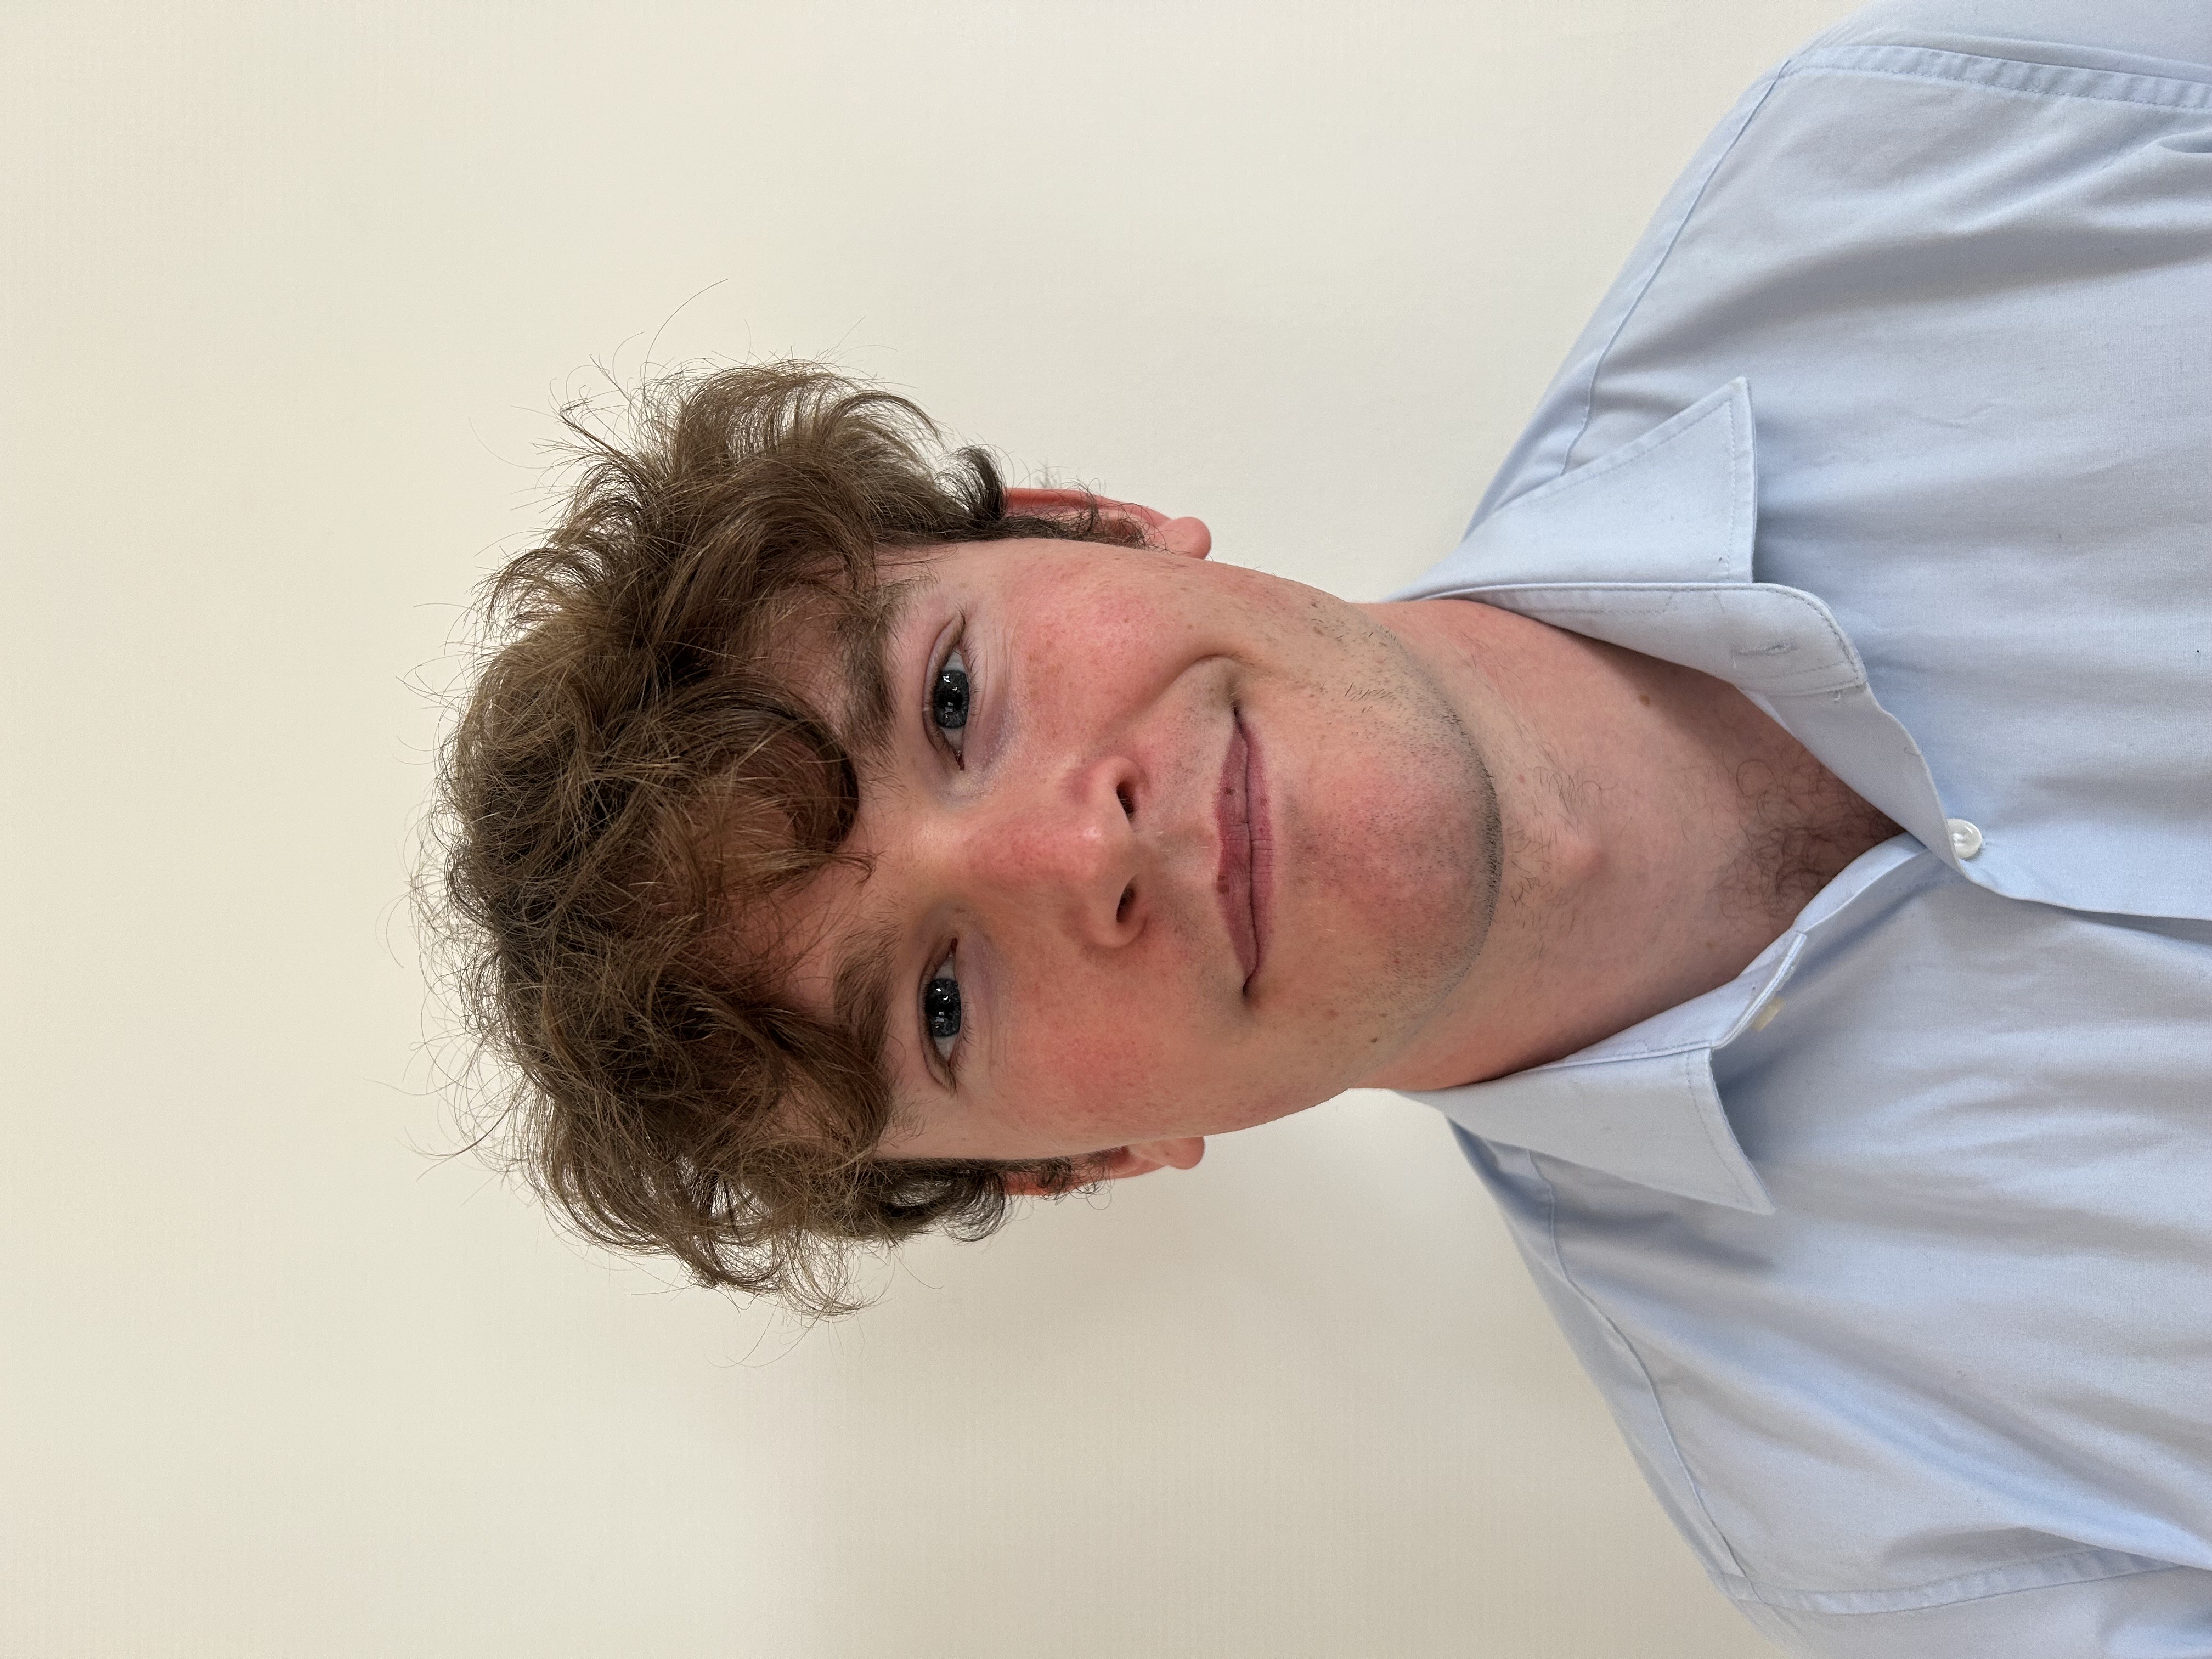
Calum Hall, 2024
|
Hi! My name is Calum Hall. I'm a recent graduate of the University of St Andrews.
Currently working at Accenture as part of the Modern Engineering Graduate Scheme.
I have a strong foundation in software development and enjoy tackling complex problems
and transforming ideas into efficient code. I also have experience in Cybersecurity
from an internship in the threat detection team at Lloyds Banking Group.
My other interests are guitar, rugby and reading! :-)
>> CLICK HERE TO DOWNLOAD MY CV <<
|
|
|
>> What I'm Working On
|
[IN PROGRESS]
Portfolio Website on OCI
Building this website using web technologies and hosting it on Oracle Cloud Infrastructure.
Implementing infrastructure as code with Terraform and automated deployments via CI/CD pipelines.
Skills used:
HTML/CSS/JS | OCI | Terraform | GitHub Actions
|
[COMPLETED]
FlatFinder — a polite, robots.txt-respecting flat search monitor
>> The Problem
I was flat-hunting in north London: a 3-bed/2-bath around £3,500pcm in a handful of outcodes,
ranked by my own priorities rather than whatever order a portal's search results happened to load in.
Checking five portals by hand every morning, cross-referencing against what I'd already seen, was the
actual bottleneck — not a lack of listings.
>> Why It Isn't a Scraper
Rightmove and Zoopla both prohibit automated collection in their terms — Rightmove has litigated
over it — and both sit behind bot detection that blocks an IP after a few hundred requests,
browsing included. So the tool checks each portal's robots.txt at runtime and only fetches
what a generic agent is actually permitted to fetch. Anything disallowed gets a correctly parameterised
deep link instead, which you open once and attach the portal's own email alert to — genuinely the
fastest legitimate early-warning system there is, since agents push new listings to portals before they
propagate anywhere else.
That policy decision surfaced a real correctness bug: Python's stdlib urllib.robotparser
doesn't support wildcards in Disallow rules, so it silently reported SpareRoom's wildcard-only block as
"allowed" — the tool was fetching a URL SpareRoom's own robots.txt forbade, in direct
contradiction of its stated purpose. Switching to protego (the spec-correct parser Scrapy
itself uses) fixed it. It's the kind of bug that only shows up if you go looking for it, since the
failure mode is permissive, not a crash.
>> What the Tool Actually Does
Dedupe, scoring, and reporting work identically regardless of which portals a given run could fetch.
Listings are geocoded (full postcode if stated, else the outcode's centroid via postcodes.io) and given
a real door-to-desk commute time from TfL's Journey Planner, rather than a static per-outcode guess
— falling back to that guess, explicitly labelled, only when a listing can't be geocoded.
Everything is scored against configurable weights (value, commute, pubs, green space) and rendered as a
single page with new listings since the last run flagged. Flags — "only 1 bathroom", "bathrooms
unconfirmed" — are surfaced rather than used to filter listings out silently.
>> From Script to Unattended Service
The last piece was making it run itself: daily, in the cloud, emailing the result. That meant an OCI
Function on a Resource Scheduler cron trigger — Functions have no persistent filesystem, so run
state (seen.json) round-trips through an Object Storage bucket on every invocation, while the
existing CLI code runs completely unmodified (its file paths are module-level globals the function
handler just repoints at /tmp before calling straight into the same collect/score/report
pipeline).
Two things broke in ways that were only obvious once real mail was inspected: the report's JS-powered
filter bar doesn't survive email clients stripping <script>, so the mailed version became a
separate, script-free digest — new listings only, linking back to the full interactive report
hosted via a pre-authenticated Object Storage URL. And that link initially loaded as raw text instead
of a rendered page, because Object Storage's put_object defaults to
Content-Type: application/json when you don't set one explicitly — true regardless of
what you're actually uploading.
>> Outcome
Found the flat, signed the lease, decommissioned the schedule.
Skills used:
Python | requests | BeautifulSoup | protego |
TfL Journey Planner & postcodes.io | OCI Functions | Object Storage
| Resource Scheduler | IAM | Docker | Gmail SMTP
>> VIEW ON GITHUB <<
|
|
GitHub
|
LinkedIn
|
Email Me!
|